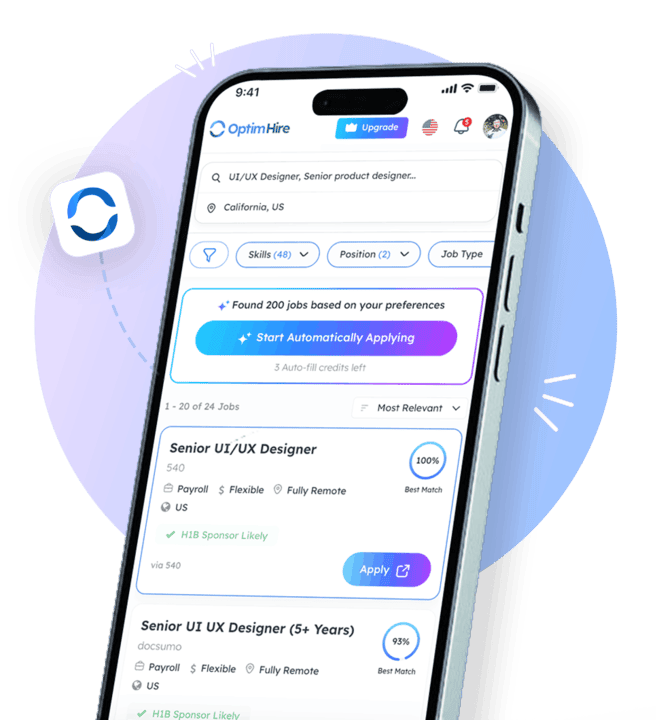
 We're excited to introduce the all new OptimHire Mobile App

OptimHire’s Job Auto-Applier that will automatically apply to jobs at 300,000+ Companies.
Azure Data Engineer
Candidate Skills and Qualifications:
• Experience: 6 to 8+ years as an Azure Data Engineer, with a strong focus on Azure Databricks and PySpark.
• Data Pipeline Development: Proven expertise in designing, developing and maintaining complex data pipelines on Azure platforms.
• Data Migration: Experience in migrating data from on-premises and cloud-based systems to Azure, ensuring seamless data integration.
• Data Modeling: Proficient in dimensional data modeling and designing data warehouses for efficient data storage and retrieval.
• Azure Services Proficiency: Hands-on experience with Azure Data Factory, Azure Databricks, Azure Synapse Analytics, Azure Data Lake and Azure SQL Database.
• Programming Skills: Strong proficiency in Python and SQL; familiarity with Scala is advantageous.
• Big Data Frameworks: Experience with big data frameworks, particularly Apache Spark, for large-scale data processing.
• Version Control and CI/CD: Familiarity with Azure DevOps, Git and implementing CI/CD pipelines for automated deployments.
• Security Practices: Knowledge of Azure security practices, including Azure Active Directory (AAD), Key Vault and Role-Based Access Control (RBAC).
Role & Responsibilities
• Data Pipeline Management: Design, develop and maintain complex data pipelines on Azure to support business requirements.
• Data Migration: Migrate data from on-premises and cloud-based systems to Azure platforms, ensuring data integrity and security.• Data Modeling and Warehousing: Implement and optimize dimensional data models and data warehouses for scalable and efficient data processing.
• Azure Services Utilization: Work extensively with Azure Data Factory, Azure Databricks, Azure Synapse Analytics, Azure Data Lake and Azure SQL Database to manage and process large datasets.
• Programming: Write efficient and scalable code using Python and SQL to support data engineering workflows.
• ETL/ELT Processes: Develop and maintain ETL/ELT processes, leveraging big data frameworks such as Apache Spark for large-scale data processing.
• CI/CD Implementation: Set up and manage Azure DevOps pipelines, Git repositories and CI/CD processes for seamless deployment and automation.
• Security Compliance: Ensure compliance with Azure security best practices, including implementing AAD, Key Vault and RBAC for secure data access.
• Collaboration: Collaborate with cross-functional teams to identify, develop and implement data solutions to meet organizational needs.
• Monitoring and Troubleshooting: Monitor and troubleshoot data workflows, ensuring high performance and reliability.
Preferred Candidate Profile
• Experience: Minimum of 5 years as an Azure Data Engineer.
• Certifications: At least one relevant certification, such as the Microsoft
Certified: Azure Data Engineer Associate.
• Azure Data Services: In-depth knowledge of Azure data services, including Data Factory, Databricks, Synapse Analytics, Data Lake and SQL Database.
• Programming Skills: Strong programming skills in Python and SQL; familiarity with Scala is a plus.
• Data Modeling and ETL: Expertise in data modeling and ETL/ELT processes.• Big Data Frameworks: Hands-on experience with big data frameworks, such as Apache Spark.
• Version Control and CI/CD: Familiarity with Azure DevOps, Git and CI/CD implementation.
• Security Practices: Understanding of Azure security practices, including Azure Active Directory (AAD), Key Vault and Role-Based Access Control (RBAC).
• Analytical Skills: Strong analytical and problem-solving abilities.
• Communication: Excellent communication and teamwork skills.
• Adaptability: Ability to adapt to changing business needs and work effectively in an offshore setup.
DevOps Engineers
Data Scientist
Cloud Architects
Systems Analysts
Data Engineer
Azure - 5 years
Azure DataBricks
PySpark
Azure Data Factory
 Get the OptimHire App
Search smarter, apply faster, and track application on the go with the OptimHire App.

AI Powered
Job Search

Access to
10M Jobs

Auto-Apply
to Job

AI Powered
Custom Resumes


 Refer & Earn