Get 10x More Interviews Without Applying Manually | OptimHire

OptimHire
OptimHire Job Auto-Applier
★★★★★
Install
We're excited to introduce the all new OptimHire Mobile App
Trusted by 50,000+ job seekers
Looking to Hire?

Senior Software Engineer Distributed Data Systems

Refer and Earn up to $200 USD

Refer & Earn

Get 10x More Interviews
Without Applying Manually

OptimHire’s Job Auto-Applier that will automatically apply to jobs at 300,000+ Companies.

★ ★ ★ ★ ★
Trusted by 50,000+ job seekers

Description

Job Description

About the Role

We are seeking a Software Engineer to design and build high‑performance distributed data ingestion systems. You will work on parallel processing pipelines that integrate with cloud storage, relational databases, and streaming platforms. This is a core product development role where you’ll apply best practices in distributed system design, ensuring scalability, reliability, and performance.

Key Responsibilities

  • Design and implement data ingestion pipelines with parallel processing in Java, C++, or Golang.
  • Ingest data from Amazon S3, Azure Cloud Storage, Google Cloud Storage, Snowflake, BigQuery, PostgreSQL, files, Kafka, and Iceberg data lakehouse.
  • Build high‑availability (HA) loading systems with cross‑region replication.
  • Develop monitoring and error reporting for ingestion pipelines.
  • Integrate with Spark connectors and manage third‑party systems (Kafka, Kafka Connect).
  • Collaborate with cross‑functional teams to ensure scalable, reliable, and performant distributed systems.
  • Follow Agile development practices and contribute to CI/CD pipelines.


Requirements

Requirements

  • Strong programming skills in Java, C++, or Golang.
  • Hands‑on experience with Kafka, Zookeeper, Spark, or stream processing frameworks.
  • Expertise in Kafka Connect, Kafka Streams, Kafka security, and customization.
  • Experience with Spark connectors and event‑driven architectures.
  • Familiarity with Agile development and CI/CD workflows.

Nice to Have

  • Experience with gRPC protocol and multi‑threading.
  • Exposure to Zookeeper, ETCD, or Consul.
  • Understanding of distributed consensus algorithms (Paxos/Raft).
  • Knowledge of Docker and Kubernetes for containerized deployments.


Position

Data Engineer

Backend Engineer

Platform Engineer

Must have skills

Apache-Kafka - 3 years

AWS - 4 years

Kubernetes - 4 years

Nice to have skills

Java - 6 years

C++ - 5 years

Go Lang - 5 years

Zookeeper - 3 years

Apache Spark - 3 years

Security Management - 2 years

Agile Software Development - 3 years


About the Company

Anew-age AI-First Digital and Cloud Engineering services company

Perks

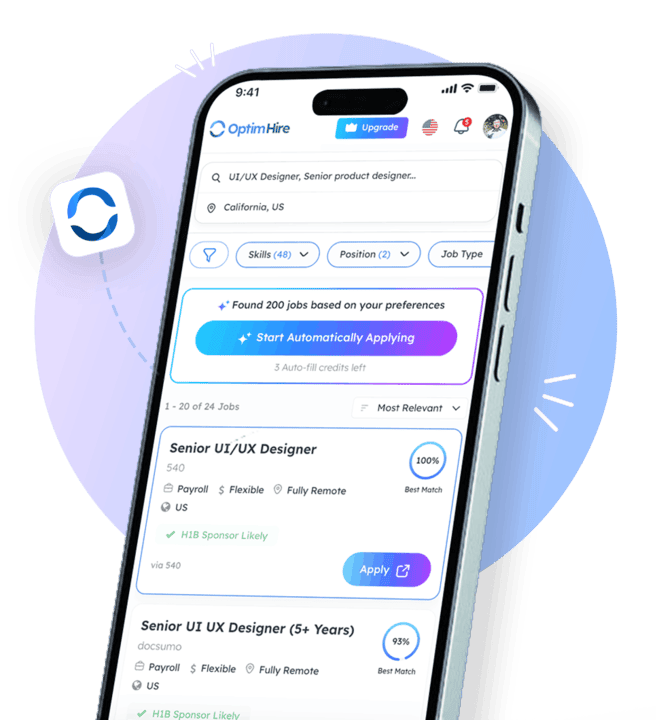
Access to 10M Jobs Get the OptimHire App

Your Dream Job is
Just a Tap Away

Search smarter, apply faster, and track application on the go with the OptimHire App.

AI Powered Job Search

AI Powered
Job Search

Access to 10M Jobs

Access to
10M Jobs

Auto-Apply to Job

Auto-Apply
to Job

AI Powered Custom Resumes
AI Powered
Custom Resumes

Trusted by 50,000+ job seekers
OptimHire App Preview