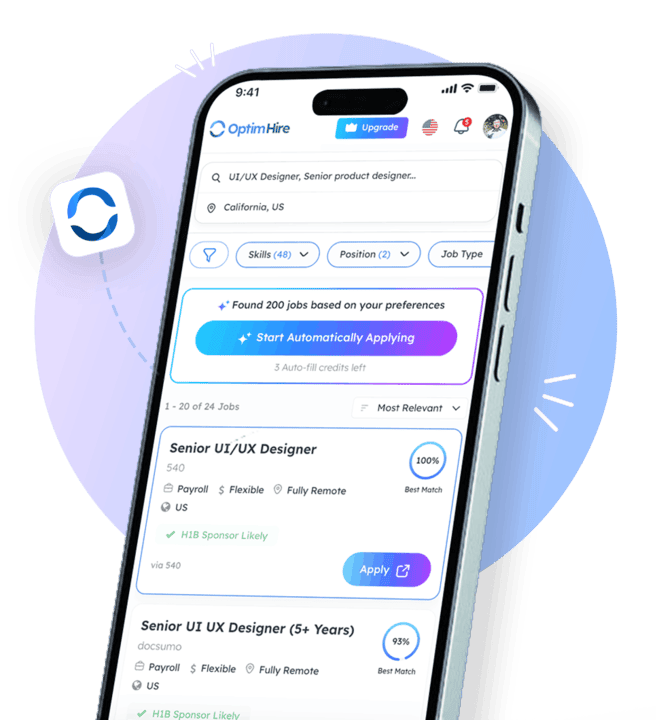
 We're excited to introduce the all new OptimHire Mobile App

OptimHire’s Job Auto-Applier that will automatically apply to jobs at 300,000+ Companies.
Job Title: Fabric Data Engineer
About the Role
We are looking for a hands-on Fabric Data Engineer who thrives in the details — someone who
writes the PySpark, builds the pipeline, creates the table, and owns it end to end in production.
This is not an advisory role. You will be deep in Microsoft Fabric and Azure Databricks daily,
engineering the data foundations that power enterprise applications and Power BI reporting at
scale.
You bring strong Python and PySpark skills, understand the Fabric ecosystem inside out, and
know how to structure data so that both applications and analysts can consume it cleanly
without workarounds. You care about pipeline reliability, data quality, and the kind of logging
and alerting that means your team sleeps well at night.
Key Responsibilities
Microsoft Fabric & OneLake Engineering: Design, build, and maintain data lakehouses on
Microsoft Fabric
Azure Databricks Development Build and maintain Spark-based transformation pipelines in
Databricks using PySpark and Python, following a modular, testable code structure.
Consumption Layer for Applications & Power BI Design and deliver a clean, stable
consumption data layer
Pipeline Monitoring & Maintenance
Logging Framework
Alerting Mechanism
Python - 4 years
PySpark - 3 years
Data Engineer - 5 years
Microsoft Fabric - 3 years
Azure DataBricks - 3 years
Big Data - 2 years
OneLake Engineering - 3 years
 Get the OptimHire App
Search smarter, apply faster, and track application on the go with the OptimHire App.

AI Powered
Job Search

Access to
10M Jobs

Auto-Apply
to Job

AI Powered
Custom Resumes


 Refer & Earn